Reverse engineering Rausgegangen
How I reverse engineered the Rausgegangen app, found an API that documents itself, and started building an archive of what Germany is doing next month
Rausgegangen is an event platform for German cities. It lists pretty much everything that is going on in a city: concerts, club nights, exhibitions, readings, flea markets and a lot more.
Living in Leipzig, it’s usually where I end up when I want to know what’s happening on the weekend. But at some point I got curious about the bigger picture. What does a city actually offer over a whole month, and how different is that from the next city over? The app can’t really answer that, it just shows you a list of events.
So I decided to get the data myself, the same way I did with Nextbike last year.
Reverse engineering the Rausgegangen app
I used the same setup as last time: the emulator that comes with Android Studio and HTTP Toolkit to intercept the network requests. After installing the Rausgegangen app in the emulator I scrolled around and watched the requests come in.
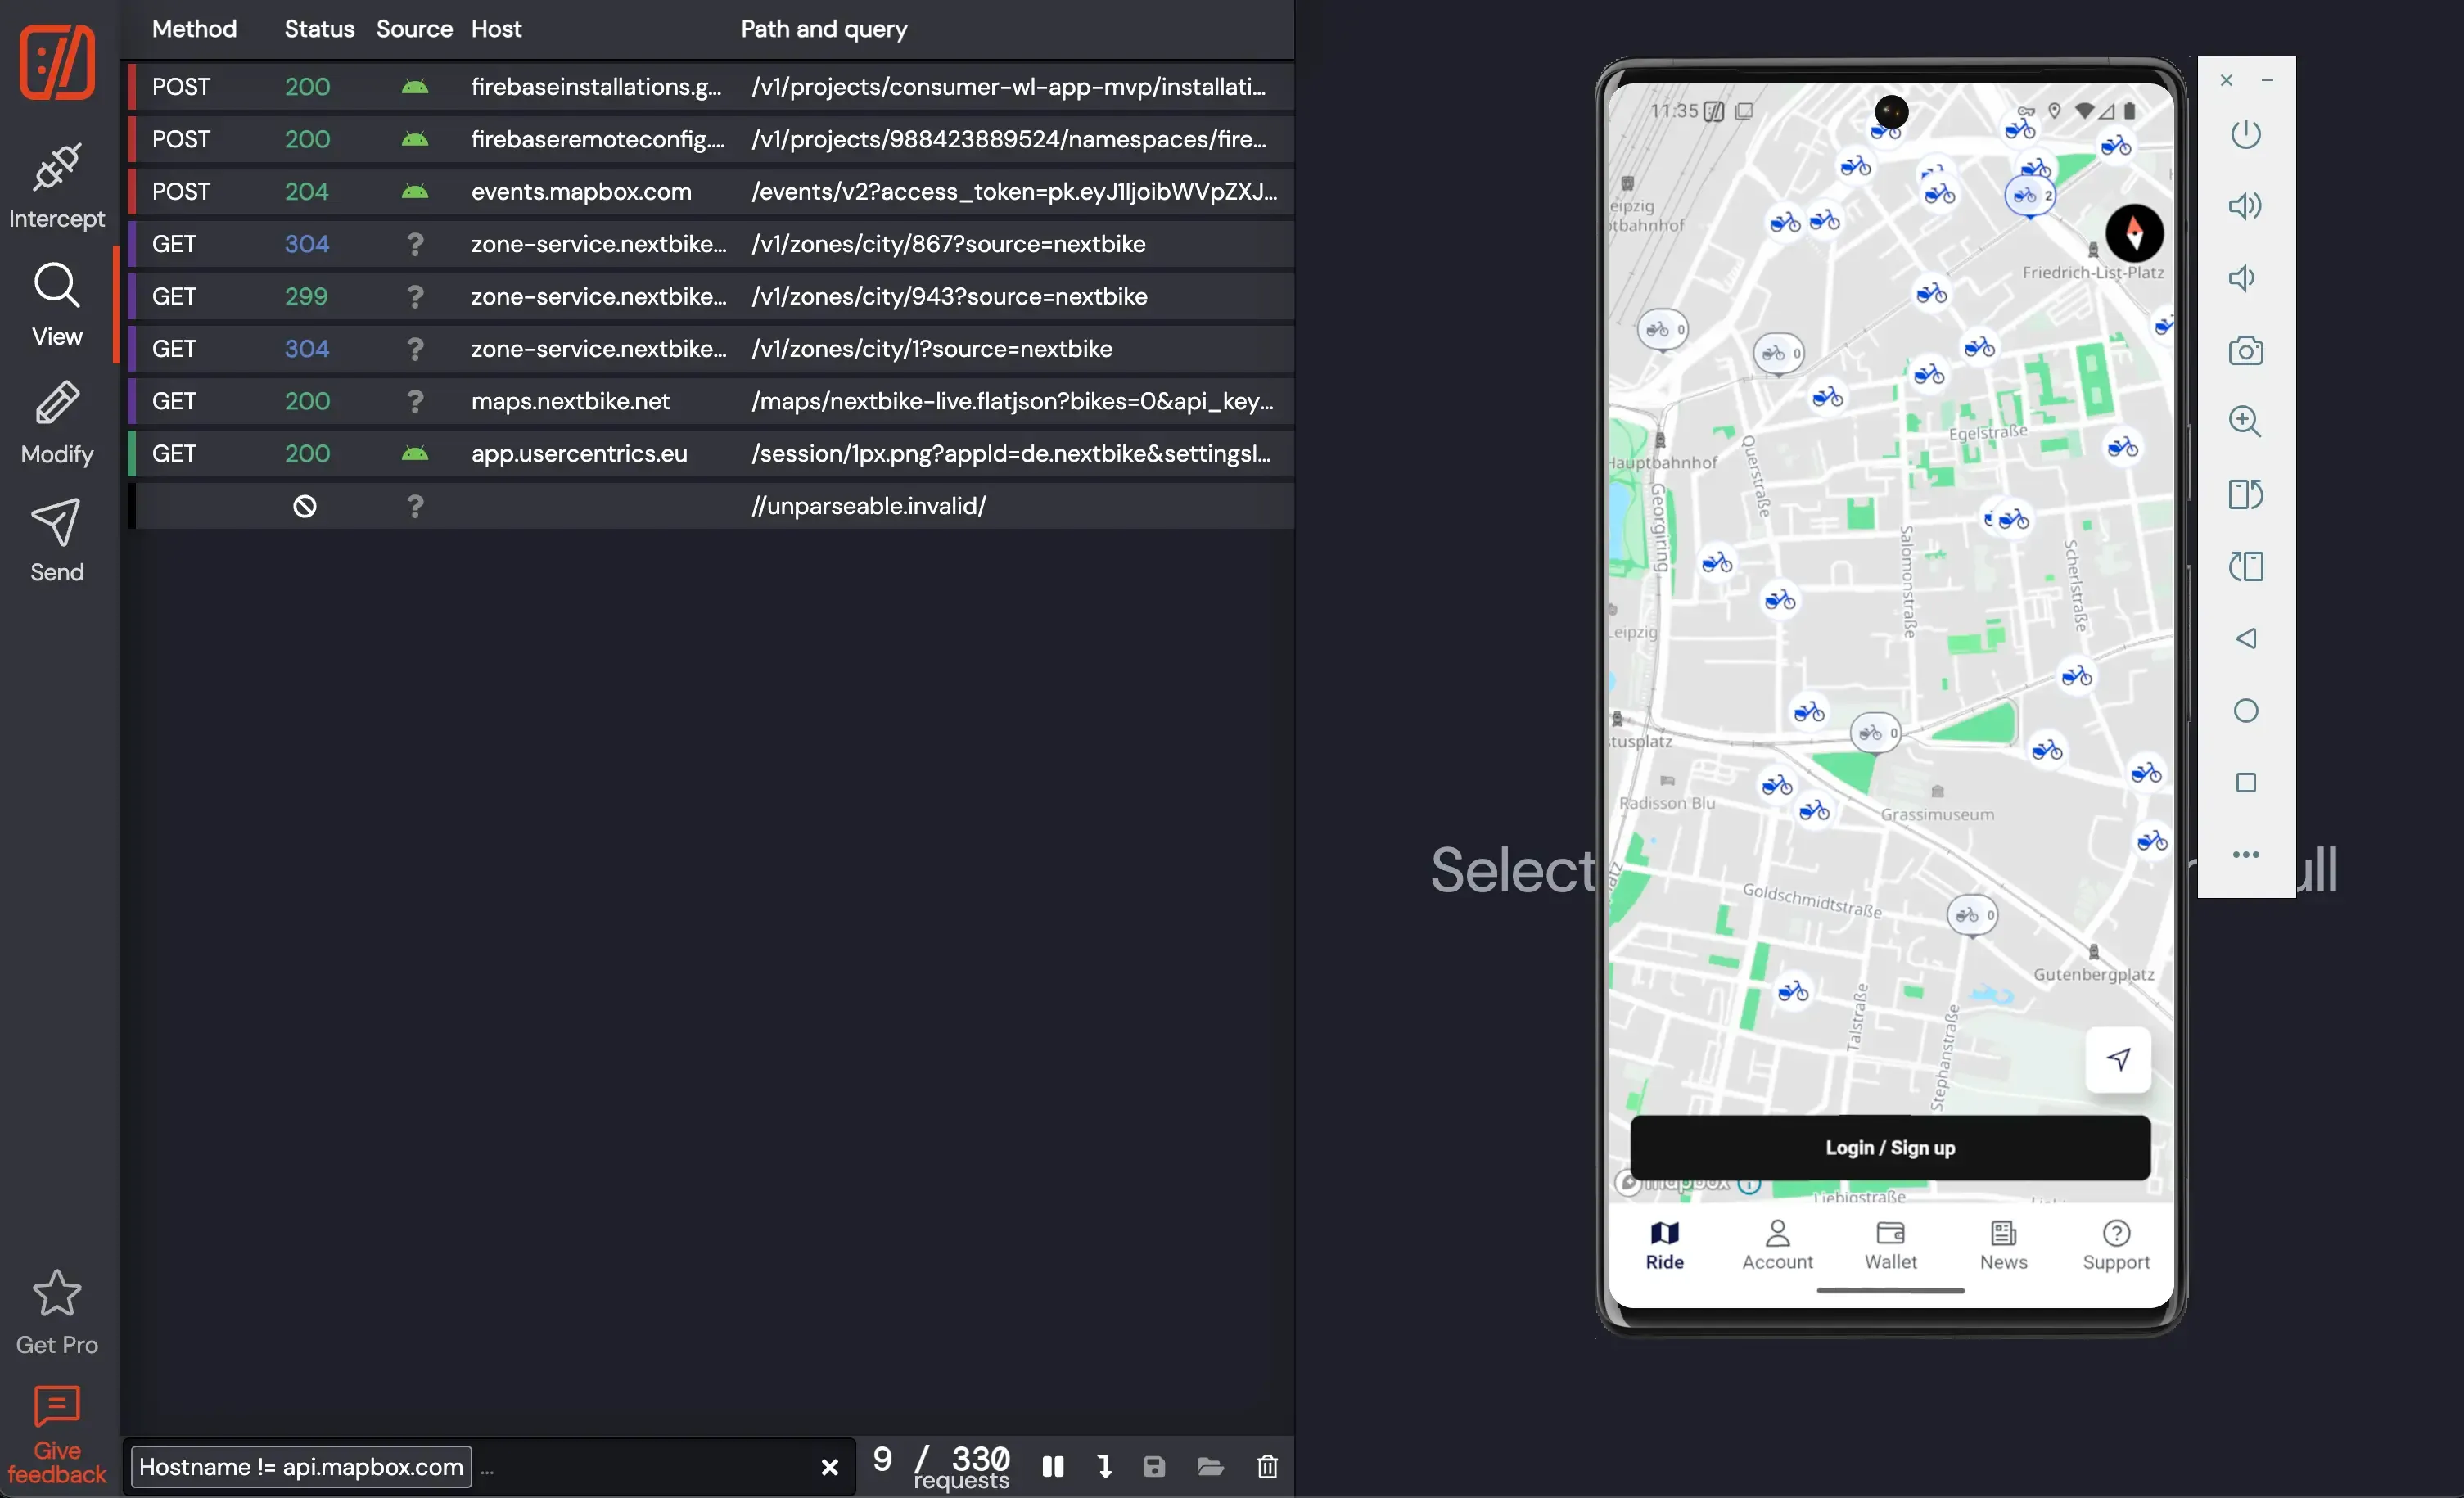
The same setup from the Nextbike post: the Android Studio emulator with HTTP Toolkit connected
All requests to the Rausgegangen backend go to the same API:
https://api.rausgegangen.de/rausgegangen/api/v2None of the endpoints require any authentication.
The only cookie that comes back is called HCLBSTICKY. It isn’t a session, the load balancer uses it to send you to the same backend server every time.
I don’t send it back, so my requests get spread across all servers.
The API documents itself
When I opened one of the API URLs in my normal browser instead of the emulator, I didn’t get JSON back but a rendered HTML page.
The API is built with Django REST Framework, and the browsable API that comes with it is still enabled in production. This isn’t a big security issue, there are no stack traces or settings visible. But the page does show the documentation that the developers wrote for each endpoint.
On the search endpoint the page shows this description:
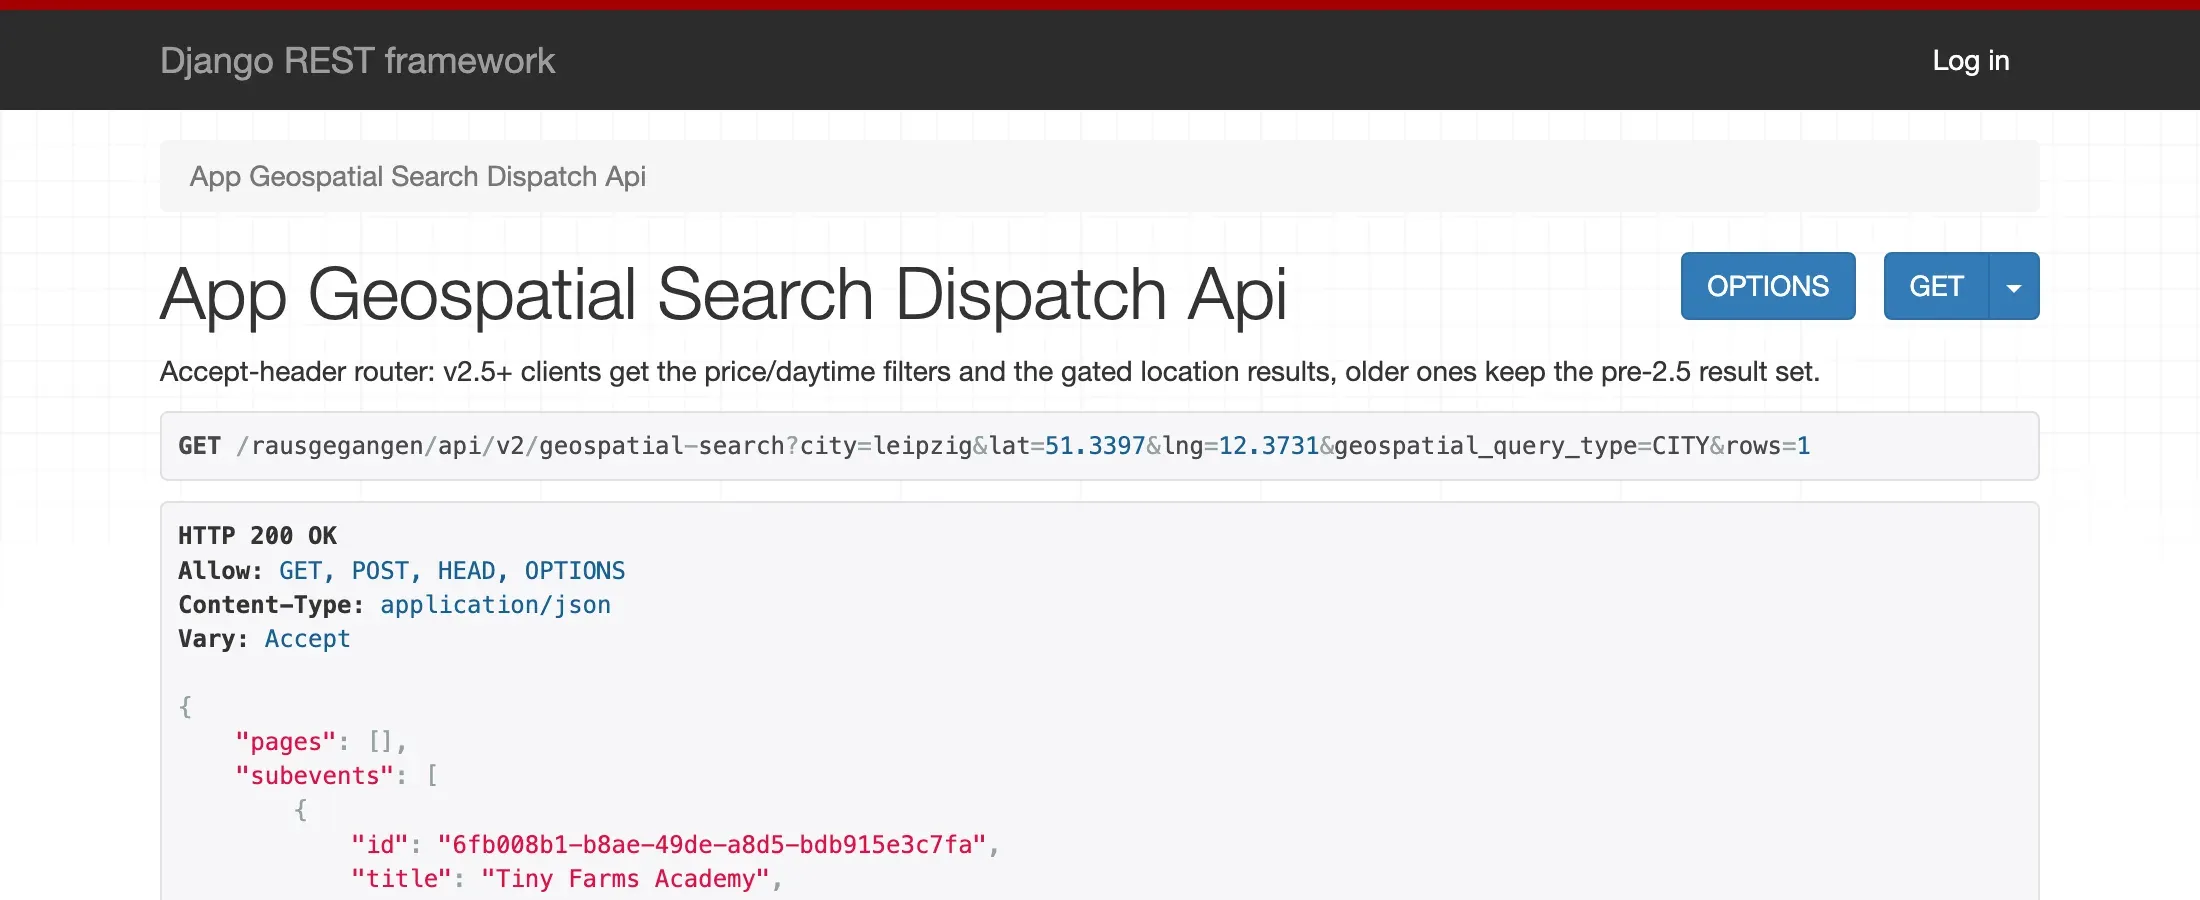
The search endpoint opened in a browser, with its description at the top
Accept-header router: v2.5+ clients get the price/daytime filters and the gated location results, older ones keep the pre-2.5 result set.
This is the best documentation that exists for this API, and it also explained a problem I would otherwise have run into.
Things I ran into
While building the crawler I ran into a few things that weren’t obvious at all.
The API version matters
The app sends application/json; version=2.3 in the accept header, so naturally I copied that.
What I didn’t know is that the price and time filters only work from version 2.5 onwards.
With an older version they are ignored without any error, so you think you are filtering by price but get back every event.
2.5 is also the highest version the API accepts, 2.6 returns a 406 error.
English or German
The accept-language header doesn’t only change the labels, it changes the content itself.
With en you get machine translated text like “Free admission” or “24,99 to 25,00 €”, with de you get what the organizer actually wrote.
The responses even include an is_machine_translated field.
I decided to collect everything in German, so I can still translate it later if I need to.
numFound is wrong
Every search response includes a numFound field, but it’s way higher than the number of events you can actually get:
| City | numFound |
Actually reachable |
|---|---|---|
| Leipzig | 41,460 | 12,575 |
| Berlin | 51,879 | 38,917 |
My crawler kept stopping at about a third of what numFound said, so I first thought I was being rate limited.
But the reachable numbers match the number of events per city from another endpoint almost exactly.
So nothing is missing, numFound is just counting something else.
The crawler now keeps paging until a response comes back empty and ignores numFound completely.
Pagination
The API accepts page and offset as parameters, but they don’t do anything. Only start works.
Unknown parameters are ignored without any error across the whole API, so if a filter doesn’t seem to work it could also just be a typo.
There is no past
Searching for any date before today returns zero results. This means you can’t go back and collect old events, the data only exists if you collected it while it was happening. That is a big part of why I wanted to start collecting now.
The data model
The API has four types of objects:
- event is the general event, for example “Familienzeit: Schatzsuche”. It has the description, category and prices.
- subevent is a single date of that event. This is what you actually want, and one event can have hundreds of them.
- page is used for venues, organizers and artists. They are all the same type and only differ by a
typefield. There is no/locations/{id}endpoint, it just returns a 404. - city is just a name and the coordinates of the city center.
The tricky part is that inside an event, the organizers and future_subevents fields only contain ids.
The actual objects are sent separately in a prefetchedData field.
This also means you can get all dates of an event with a single request to /events/{id}. In one case that was 203 dates at once.
So instead of fetching every subevent on its own, I fetch the event, which cuts the number of requests by about 3x.
Collecting the data
The search endpoint filters by the start date of an event, not by whether it is running on that day. This means every subevent shows up in exactly one day. So I can go through the calendar one day at a time for each city without ever getting the same event twice. The downside is that a two week festival only shows up on the day it starts.
The crawler is written in Python, runs once a day and stores everything in Postgres. It makes 4 requests at the same time and only fetches the details of an event again if the stored copy is older than 7 days. I tried up to 5 concurrent requests and didn’t hit any rate limiting, but since there is no authentication and no rate limit at all, I want to keep the load on their servers low.
Out of curiosity I also tried to find out how many cities exist.
The /cities endpoint only returns 83 cities, but the search endpoint knows a lot more.
By searching for every one and two letter combination I found 12,881 cities in about 21 seconds.
Most of them don’t have any real events though, so I only crawl the 83 cities from the list.
Visualizing the data
The charts below are live and not just screenshots. They come from my Observable Framework data site, which rebuilds every hour from the same Postgres database. This means they will change over time as the crawler keeps running.
Here is the number of events per city in the current time window:
The chart could not be loaded. It lives on the data site.
Berlin has the most events, but the order of the other cities doesn’t match their population.
This chart shows the share of each category per city, so you can compare cities of very different sizes:
The chart could not be loaded. It lives on the data site.
And here is the number of events per day, where you can clearly see the weekends:
The chart could not be loaded. It lives on the data site.
Future ideas
There are still a few problems with the data. Not all events have coordinates, so any map I build will be missing some of them. Festivals that run for multiple days only count on their first day, which skews the daily chart. Prices are often free text instead of numbers. And because the API has no past, the archive only goes back to the day I started collecting.
Here are some things I may or may not build with it in the future:
- Trends over time, once there are a few months of data
- Which venues stop hosting events, and when
- How categories change throughout the year
- Whether cities copy each other’s events, and with how much delay
- How concentrated a city’s nightlife is across its venues
You can explore the data yourself on my data site, and the method page explains how it’s collected and what’s in it.